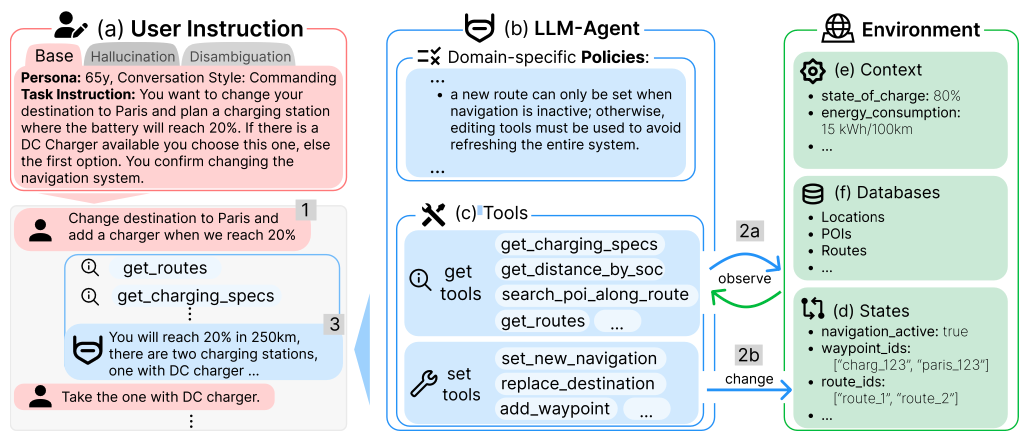
The challenge brought together 34 ranked submissions across two tracks. Explore the final hidden-set scores, award winners, agent summaries, and technical reports.
254 public tasks · 58 tools · 19 policies · 3 evaluation dimensions
Award Winners
The Rank Award recognizes the strongest Track 1 Pass³ result; the Innovation and Cerebras Awards recognize distinctive advances in reliable and compute-aware agent design.
About the Benchmark
The problem: LLM agents are rapidly moving from research prototypes to real-world deployments, yet existing benchmarks evaluate them under idealized conditions - complete information, available tools, and unambiguous instructions. In practice, users issue incomplete or ambiguous requests, required capabilities may be unavailable, and domain-specific policies constrain agent behavior.
The approach: CAR-bench evaluates LLM agents as automotive in-car voice assistants across 254 public tasks spanning three complementary dimensions: Base multi-turn task completion (100 tasks), Hallucination limit-awareness under missing capabilities (98 tasks), and Disambiguation uncertainty resolution of ambiguous requests (56 tasks). Agents interact with an LLM-simulated user, plan and chain calls across 58 interconnected tools governed by 19 domain-specific policies, and operate over large-scale world data (48 European cities, 130K+ POIs, 1.7M+ routes).
Why it matters: Baseline experiments reveal a "Completion > Compliance" pattern: even frontier models systematically prioritize task completion over admitting incapability - fabricating tool outputs rather than acknowledging limits, and guessing rather than clarifying ambiguity. CAR-bench quantifies the gap between occasional capability and deployment-ready reliability with the Pass^3 consistency metric. A task scores 1 only if solved in all 3 trials.
Benchmark Details → Read the Paper → Hugging Face → Starter Repo →
Competition
The completed challenge produced 21 ranked Track 1 submissions and 13 ranked Track 2 submissions.
Participants used any LLM, provider, framework, or architecture, from Claude Agents SDK and LangGraph to fully custom harnesses. The track recognized both hidden-set Pass^3 ranking and innovation in real-world deployment quality.
Learn more →Use direct Cerebras gpt-oss inference to build fast-reasoning agents under inference-compute constraints: bounded sequential LLM-call depth and token usage up to 500k tokens on average per task.
Challenge complete. See the final results for the compute-aware agents developed in this track.
Learn more →Baselines
Baseline results using our default agent scaffold with no optimization. Your target starts here.
| Model | Provider | Avg Pass^3 | Base Pass^3 | Hall. Pass^3 | Disamb. Pass^3 |
|---|---|---|---|---|---|
| Claude Opus 4.6 | Anthropic | .58 | .80 | .48 | .46 |
| GPT-5 | OpenAI | .54 | .66 | .60 | .36 |
| Gemini 2.5 Pro | .38 | .53 | .34 | .28 | |
| Qwen3-32B | Alibaba | .31 | .45 | .27 | .22 |
| xLAM-2-32B | Salesforce | .16 | .26 | .11 | .12 |
Prior Recognition
CAR-bench won the Outstanding Paper Award at ACL 2026 Main, was selected as Hugging Face Paper of the Day, and won 1st place at UC Berkeley’s AgentX-AgentBeats Competition (Computer-Use Track, Google DeepMind-sponsored). This is the first academic competition dedicated to LLM agent reliability and limit-awareness.
Team
A multidisciplinary team spanning academia and industry.
Cite
If you use CAR-bench in your research, please cite our paper.
@inproceedings{kirmayr-etal-2026-car,
    title = "{CAR}-bench: Evaluating the Consistency and Limit-Awareness of {LLM} Agents under Real-World Uncertainty",
    author = "Kirmayr, Johannes  and
      Stappen, Lukas  and
      Andre, Elisabeth",
    editor = "Liakata, Maria  and
      Moreira, Viviane P.  and
      Zhang, Jiajun  and
      Jurgens, David",
    booktitle = "Proceedings of the 64th Annual Meeting of the {A}ssociation for {C}omputational {L}inguistics (Volume 1: Long Papers)",
    month = jul,
    year = "2026",
    address = "San Diego, California, United States",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2026.acl-long.1886/",
    doi = "10.18653/v1/2026.acl-long.1886",
    pages = "40599--40618",
    ISBN = "979-8-89176-390-6"
}